Deep-learning services for underwater acoustics
01Raw-waveform models for underwater acoustics
Classifiers and embedding models built on SKANN, which learns its filterbank from the raw hydrophone waveform instead of a hand-set spectrogram, for closed-set classification or open-set retrieval of hulls.
02Physics-grounded synthetic training data
Synthetic underwater acoustic data for pretraining where labelled recordings run out, generated from first-principle models of ship and ambient noise, kept in physical units and verified against classical references.
03Robustness to ocean and recording conditions
Augmentation regimes that randomise recording-chain colouration, ambient noise and multipath while preserving the narrowband line structure that carries a vessel's identity.
04Evaluation that is hard to flatter
Hull-disjoint, cross-passage evaluation protocols with transit deduplication and source-pure galleries, and reporting that states what the results do and do not support.
Engagements are scoped on enquiry through the Contact page. All services across the three tracks are on the Services page; the sections below describe the methods behind them.
SKANN: a raw-waveform selective-kernel acoustic neural network
SKANN, the Selective-Kernel Acoustic Neural Network, is Oravont's deep-learning architecture for underwater audio, developed by Capt (Dr) Sunil Tyagi. It takes the raw hydrophone waveform as input, passes it through a bank of learned filters at several kernel lengths in parallel, fuses the scales with selective-kernel attention, and outputs either a hull embedding for re-identification or a calibrated class decision. It is described in his 2026 preprint (Tyagi, arXiv:2609.07399) and is the engine behind the detection, classification and vessel re-identification work on the underwater domain awareness track.
SKANN in brief: what it does, what is published, and how to use it on your own recordings →
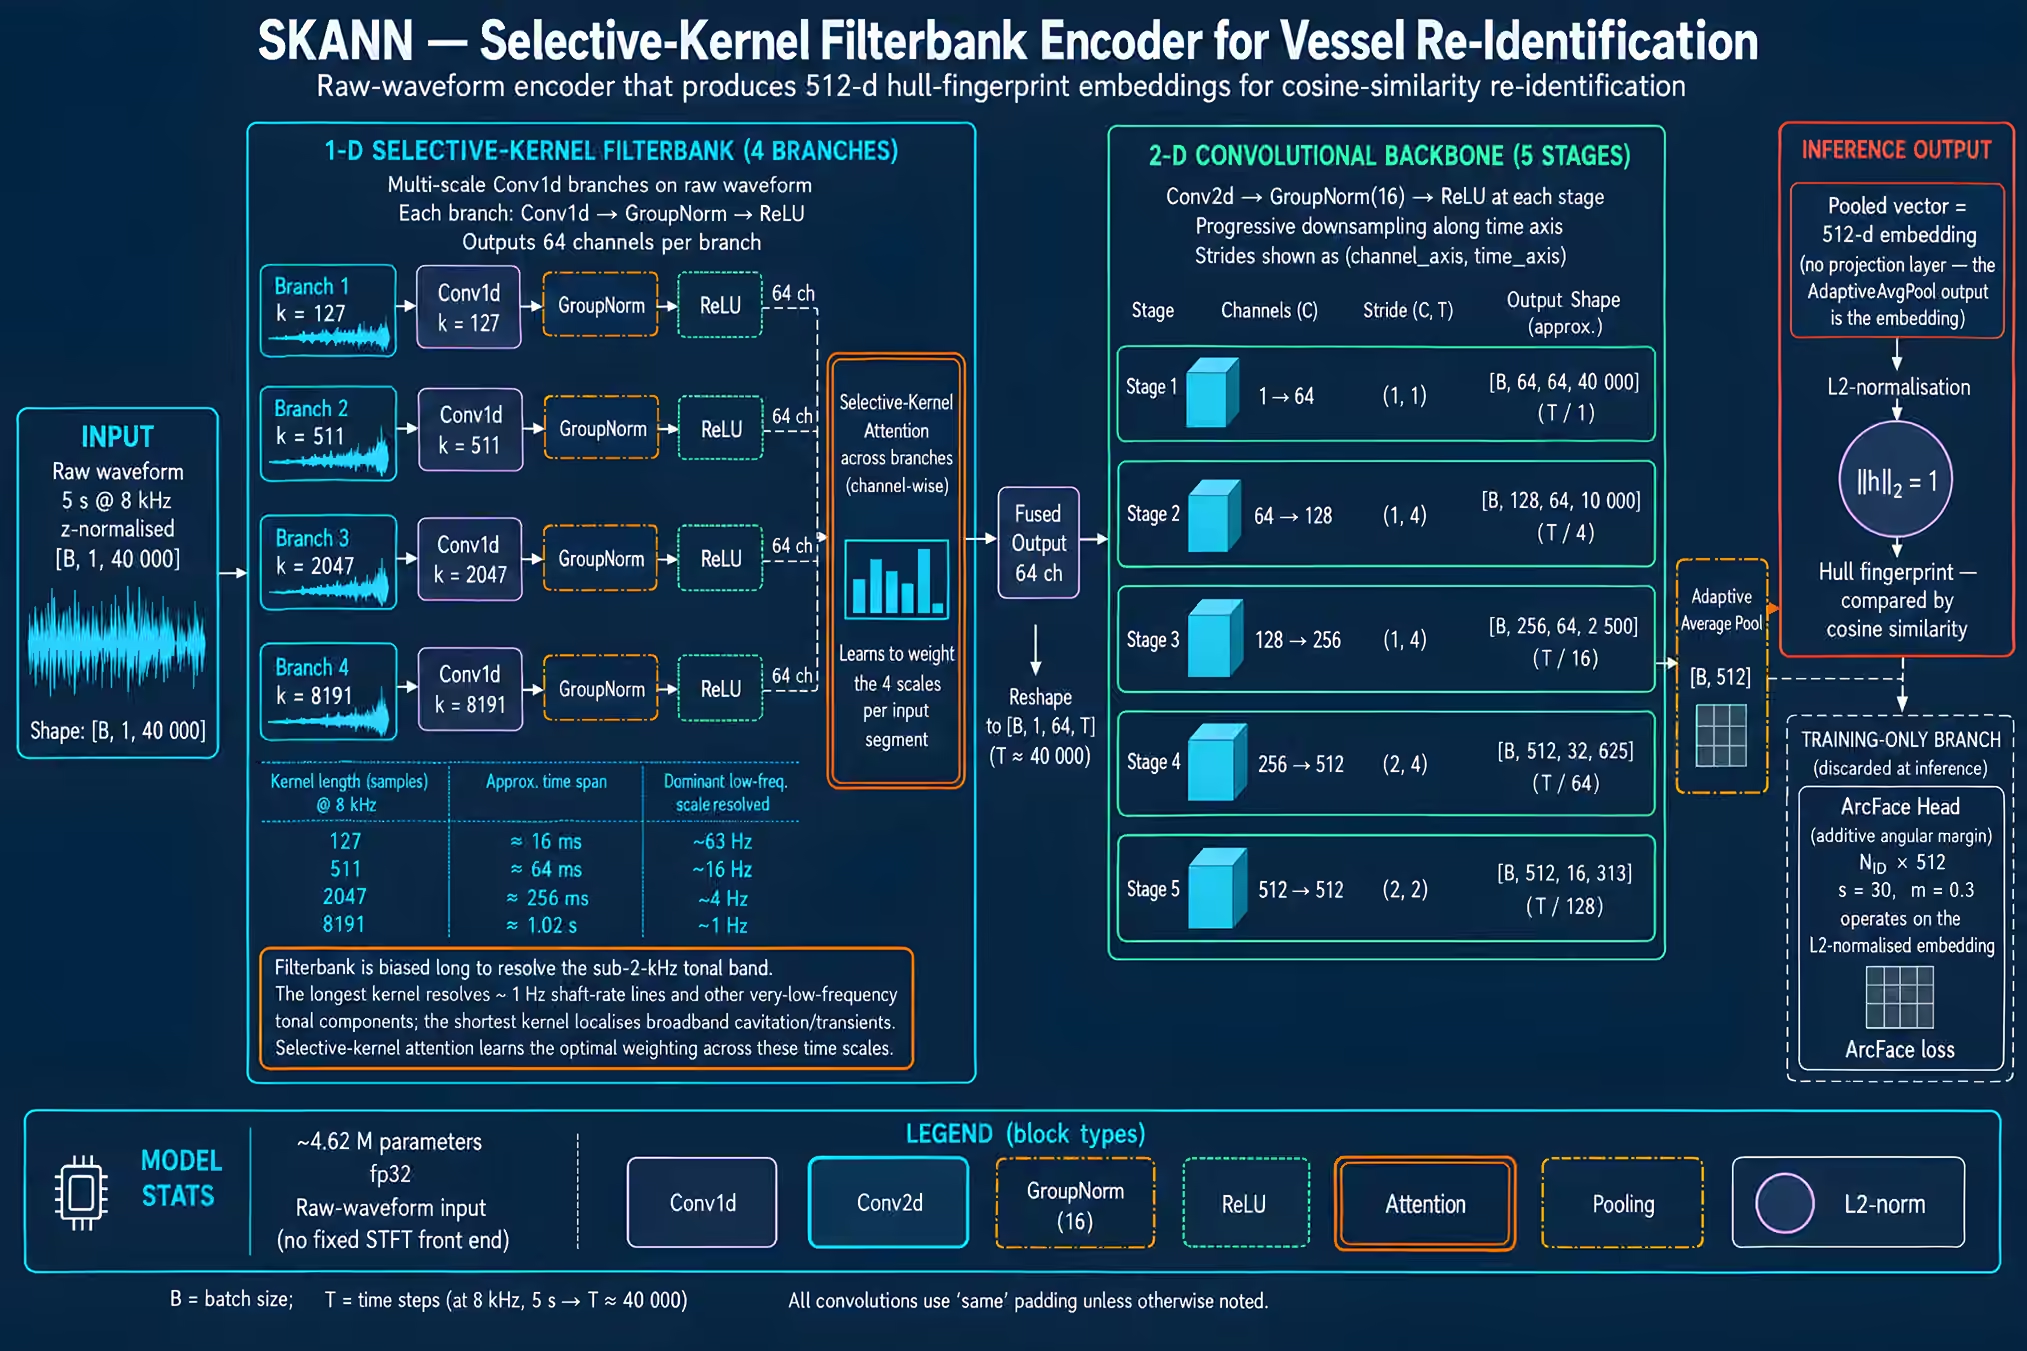
Conventional pipelines analyse spectrograms computed with a single, hand-set analysis window, yet no single window can resolve both slow machinery tonals and millisecond transients. SKANN replaces that fixed front end with a bank of dense learned 1-D filters at several kernel lengths in parallel. Long kernels capture the slow temporal structure of vessel-noise envelopes and the tonal band below 2 kHz; short kernels capture sharp transients such as clicks and snapping shrimp. Channel-wise selective-kernel attention learns which scales to trust for each input segment, and a compact 2-D convolutional backbone distils the fused feature map into a 512-dimensional embedding. No frequency band is hand-assigned; the network learns where the information lives.
The identity encoder in the 2026 preprint, shown below, has four kernel lengths from about 16 ms to 1 s and is trained with an additive angular-margin (ArcFace) objective, producing an L2-normalised hull embedding that is compared by cosine similarity. An earlier classification variant (HybridSKEncoderV3) uses eight shorter kernels, from about 0.5 ms to 64 ms, with a calibrated seven-class head; it is the classifier the PS12 pipeline runs on, and its diagram is in the capability overview.
An Indian provisional patent application (202611107132, filed 6 September 2026, applicant Oravont Systems LLP) covers aspects of the method. See Research.
The acronym SKANN is also used by Shan et al. (2025) for Selective Kernel Audio Neural Networks, a closed-set classifier of mixed ship events (CAAI Transactions on Intelligence Technology, doi:10.1049/cit2.70037). The two systems share the acronym and the selective-kernel fusion mechanism; they differ in input representation (raw waveform here), task (open-set identity retrieval here) and evaluation protocol. On this site, SKANN refers to Oravont's architecture.
Condition invariance as a property of the data
The ocean, the range and the recording chain all colour a signature. SKANN treats invariance to those conditions as a property of the training data rather than of the loss: an augmentation regime randomises recording-chain colouration, ambient noise and multipath while provably preserving the narrowband line structure that carries identity. Transforms that would move absolute line frequencies — the shaft and blade lines a stealth designer would recognise at once — are deliberately excluded, because they would erase the very evidence the model is meant to key on.
Physics-grounded synthesis where labels run out
Real underwater recordings are voluminous, unlabelled and expensive to annotate. Oravont's synthetic underwater acoustic dataset fills the gap for pretraining: 12,000 five-second clips at 16 kHz across four vessel classes — tanker, cargo ship, fishing vessel and small craft — and ambient ocean noise, generated from first-principle models with full-factorial parameter coverage. Sea noise follows piecewise Knudsen spectra by sea state; ship noise combines shaft-rate and blade-pass harmonics, generator and equipment lines, structural resonances, broadband flow noise and a physical cavitation-burst model. Every quantity is kept in physical units and verified against classical references, and the vessel classes use non-overlapping shaft-rate ranges — a decision forced by an earlier failure in downstream representation learning.
Used to pretrain an encoder with the Barlow Twins self-supervised objective, with training pairs drawn within each class, the dataset produced an embedding space that separated its classes: a silhouette score of 0.97 and 100% k-NN accuracy across five classes, as reported in the dataset article. Both figures are measured on the same clips used for training, so they are not an independent test. The dataset is released under CC BY 4.0.
Hugging Face (DOI 10.57967/hf/11191) · GitHub · Read the article · Tools & data
A protocol that closes the easy routes
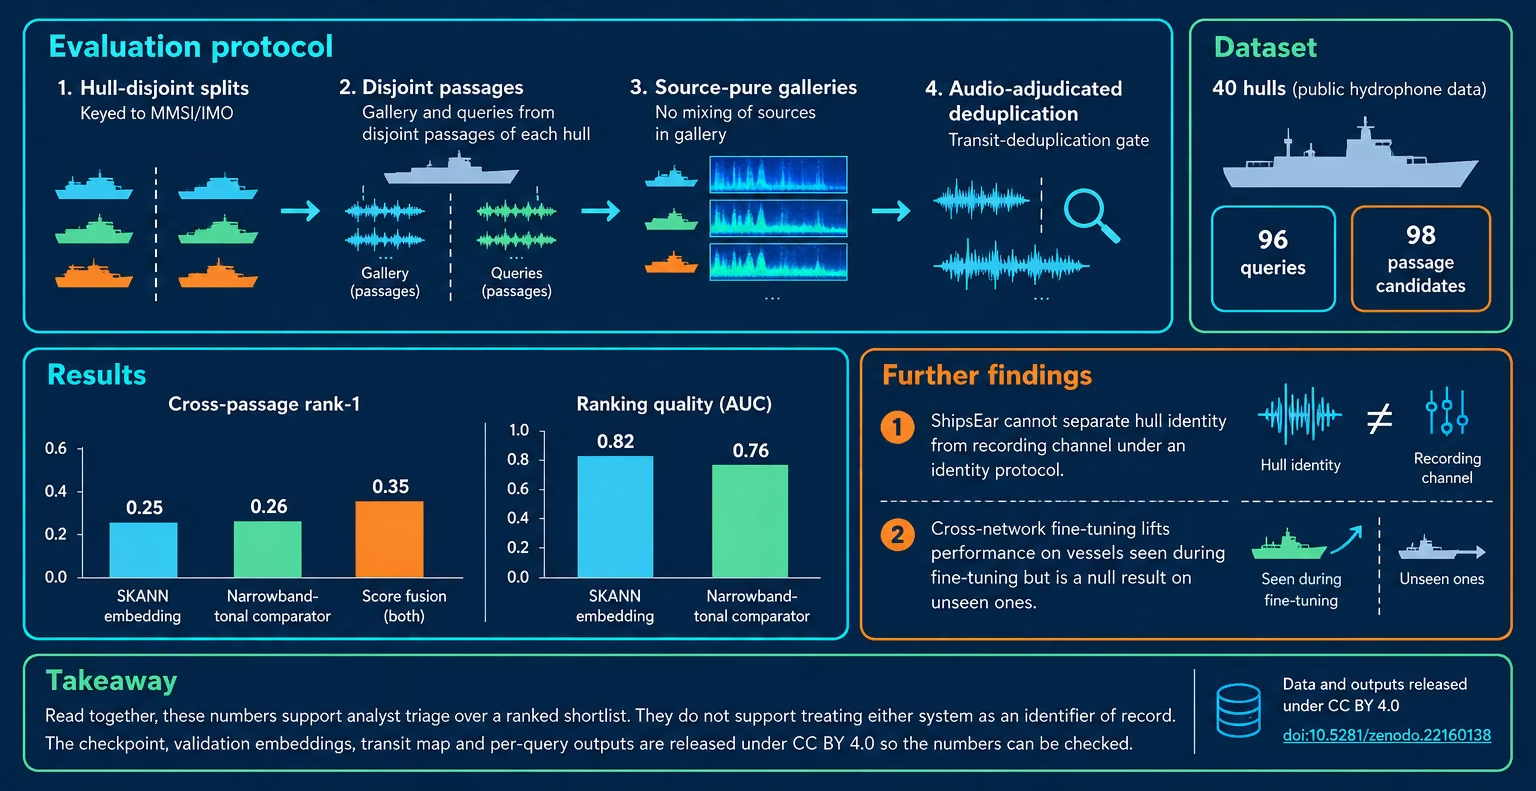
Underwater acoustic target recognition has largely settled on closed-set classification by vessel type, which does not answer whether a monitoring system has heard a particular hull before. The 2026 preprint formalises that question as open-set, cross-passage re-identification on public hydrophone data and specifies an evaluation protocol that removes the two easiest routes to a high score: hull-disjoint splits keyed to MMSI/IMO, galleries and queries drawn from disjoint passages of each hull, source-pure galleries, and an audio-adjudicated transit-deduplication gate.
On a 40-hull public gallery (96 queries against 98 passage candidates), cross-passage rank-1 is 0.25 for the SKANN embedding and 0.26 for a fully automated narrowband-tonal comparator — far below what closed-set numbers suggest, and statistically indistinguishable at the top of the ranking. The embedding orders the remainder of the list more reliably (AUC 0.82 against 0.76), and score fusion of the two reaches rank-1 0.35, the only contrast that attains nominal significance. Two further findings delimit what public data can support: ShipsEar cannot separate hull identity from recording channel under an identity protocol, and cross-network fine-tuning lifts performance on vessels seen during fine-tuning but is a null result on unseen ones.
Read together, these numbers support analyst triage over a ranked shortlist. They do not support treating either system as an identifier of record. The checkpoint, validation embeddings, transit map and per-query outputs are released under CC BY 4.0 so the numbers can be checked: doi:10.5281/zenodo.22160137.
Propagation-robust embeddings
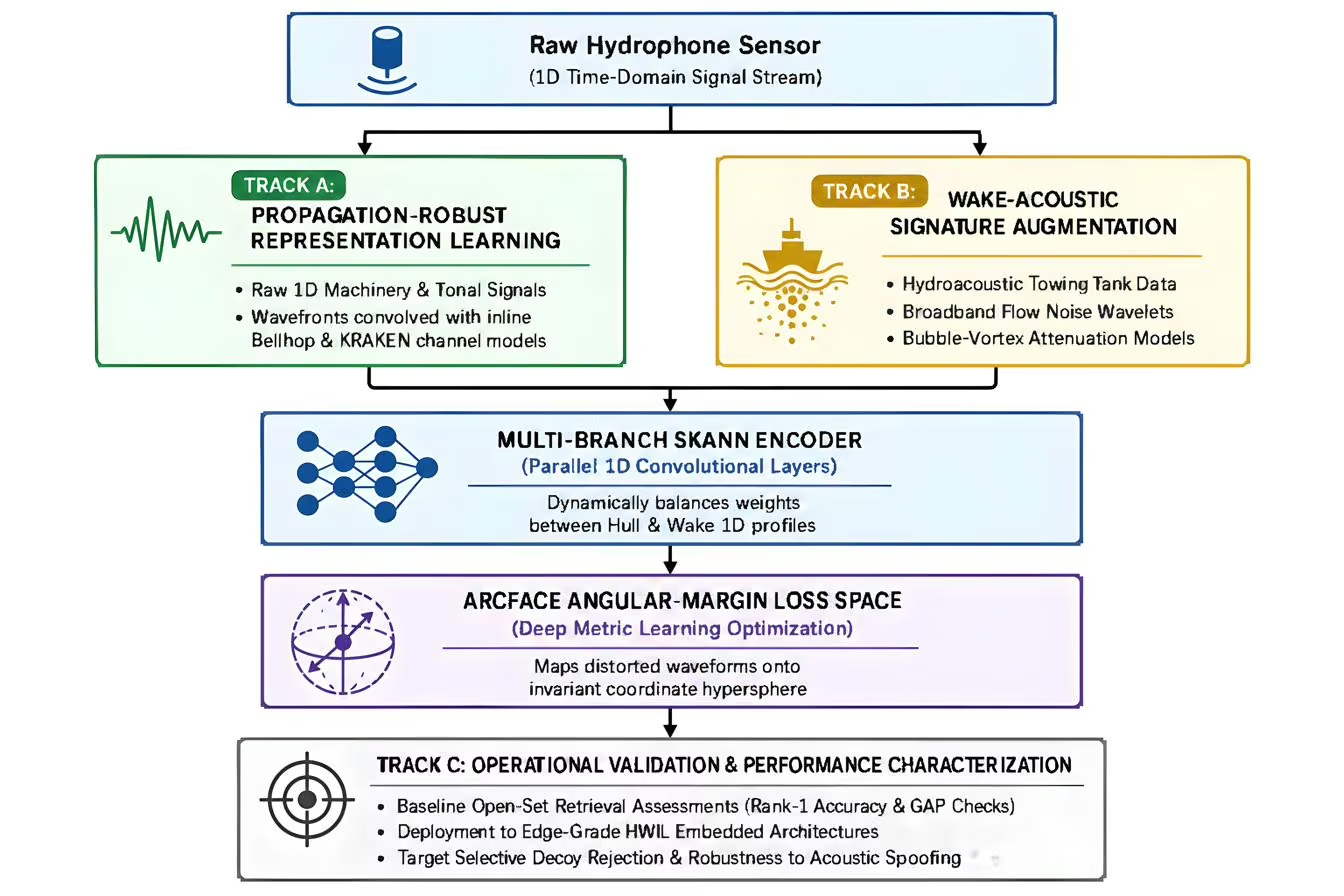
An exploratory research collaboration with IIT Delhi, in association with a DRDO/NSTL programme, extends re-identification toward propagation robustness by combining deep metric learning with physics-based acoustic-propagation modelling: the same hull, heard through different ranges, depths and sea states, should map to the same fingerprint.
Exploratory; nothing about the collaboration is finalised.
Questions this track is asked
- What is SKANN?
- SKANN (Selective-Kernel Acoustic Neural Network) is a deep-learning architecture for underwater acoustics that works directly on the raw hydrophone waveform. Its front end is a bank of learned filters at several kernel lengths, fused by selective-kernel attention; the identity encoder of the 2026 preprint spans about 16 ms to 1 s and is trained with an additive angular-margin objective to produce an embedding of a hull.
- What does SKANN stand for, and is it the same as Selective Kernel Audio Neural Networks?
- Here, SKANN stands for Selective-Kernel Acoustic Neural Network, the architecture of arXiv:2609.07399. Shan et al. (2025) use the same acronym for Selective Kernel Audio Neural Networks, a closed-set classifier of mixed ship events. The two share the acronym and the selective-kernel fusion mechanism but differ in input representation, task and evaluation protocol.
- Does it use spectrograms?
- No. The filterbank is learned from the raw waveform rather than hand-set as a spectrogram with a single analysis window, so slow machinery tonals and millisecond transients can be resolved by different kernels of the same network.
- What is open-set vessel re-identification?
- Deciding whether a monitoring system has heard a particular hull before, from its radiated noise, when the hull may never have been seen in training. On public hydrophone data the preprint's results support analyst triage over a ranked shortlist, not identification.
- Is SKANN a selective-kernel attention network?
- Yes. SKANN uses selective-kernel attention, introduced in Selective Kernel Networks (Li et al., CVPR 2019), to weight its parallel filter scales for each input. Its name, Selective-Kernel Acoustic Neural Network, reflects what it is built for: underwater acoustic signals, read from the raw waveform.
The other two tracks
Where the models go to work
Seven-class classification under PS12, open-set re-identification under DISC5, and DEMON running alongside as the transparent second opinion.
Open the track → 03 · Underwater acoustic stealthThe physics behind the training data
The acoustic-modelling know-how in the synthetic dataset and the augmentation regime — how machinery, propellers and hulls make noise — comes from stealth design.
Open the track →Work with Oravont. To discuss a project, write to info@oravontsystems.com, call +91 99222 42303 or use the contact page. Oravont Systems LLP, Noida, India.